Why Samsung’s HBM4 Expansion Starts With Glass
 by ahsan
September 20, 2026
5 min read
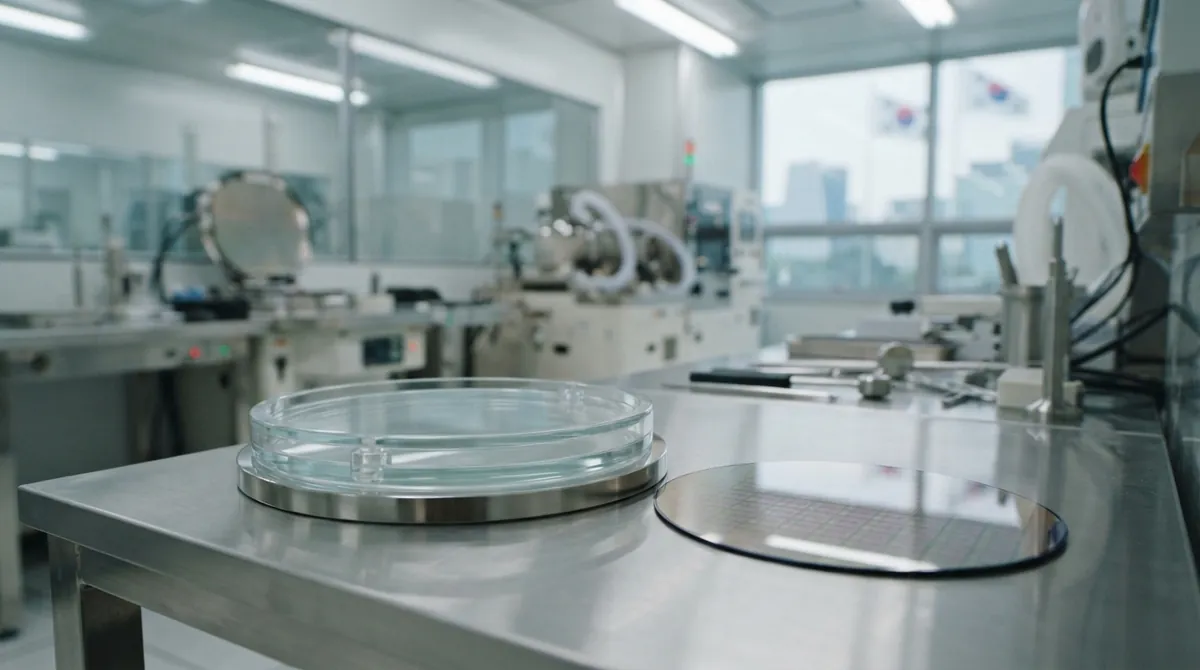
The most revealing object in Samsung’s next HBM4 expansion may not be the memory package. It may be a flat, reusable sheet of glass.
A September 20, 2026 industry report says Samsung plans to lift outsourced glass-carrier cleaning from about 20,000 sheets a month in 2026 to 50,000 in 2027. The same report points to HBM wafer input—the number of wafers entering the production flow each month—rising from roughly 180,000 to 250,000. It also projects the HBM4 family’s share of Samsung’s shipments growing from about 40% to 80%. Those are industry estimates rather than a formal Samsung unit forecast, but they spotlight a real manufacturing constraint: making memory thin enough, straight enough, and reliable enough to stack. (en.sedaily.com)
The natural search question is: why does a memory factory need more glass to make faster AI chips?
Glass is the scaffolding around thin memory
HBM stands for high-bandwidth memory. It is a form of DRAM, or dynamic random-access memory, that stores data close to a processor. Instead of spreading memory chips across a circuit board, HBM stacks several memory layers vertically and connects them to an AI accelerator through a very wide electrical interface. The goal is to move data quickly enough that the processor spends less time waiting. (semiconductor.samsung.com)
To build that stack, manufacturers start with a wafer: a round silicon disk containing many copies of a chip design. The individual pieces cut from that wafer are called dies. Before those dies can be stacked, the wafer often needs to be ground and polished from the backside until it becomes much thinner.
That creates a mechanical problem. A thin wafer is fragile and can bend, crack, or develop unwanted bowing during later processing. Semiconductor engineers call this bending warpage. A glass carrier works like a rigid clipboard: a temporary bonding layer attaches the wafer to the glass, giving it enough support to survive grinding, polishing, etching, cleaning, and other backside steps.
The carrier is not part of the finished HBM package. After processing, the wafer is separated from the glass through a debonding step, then the carrier is cleaned and returned to the production cycle. Temporary bonding and debonding are standard enablers for handling ultra-thin wafers in advanced packaging, including three-dimensional chip assemblies. (evgroup.com)
DRAM wafer
 ↓ temporary bond to glass carrier
Backside grinding, polishing, and via processing
 ↓ debond and clean
Thin memory dies
 ↓ stacking and advanced packaging
Finished HBM package
The vertical electrical paths formed through a memory die are called TSVs, short for through-silicon vias. They allow signals and power to travel between stacked layers. Keeping those layers flat and accurately aligned becomes harder as the stack grows taller, which is why a seemingly ordinary support material can become a production bottleneck.
HBM4 raises the manufacturing stakes
Samsung’s HBM4 is not merely an older memory design running at a higher clock speed. The company combines its 1c DRAM process—a sixth-generation, 10-nanometer-class manufacturing technology—with a logic base die built using a 4-nanometer process. The base die is the control layer at the bottom of the stack; it manages connections, power delivery, and communication between the memory layers and the accelerator. Samsung announced HBM4 mass production and commercial shipments on February 12, 2026. (news.samsung.com)
Samsung lists HBM4 with up to 2,048 input/output pins, or I/O pins, compared with 1,024 on the previous generation. It also lists speeds up to 13 gigabits per second per pin and aggregate bandwidth of up to 3,300 gigabytes per second per stack. Bandwidth is the amount of data that can move in a given period; in an AI system, higher bandwidth helps keep large streams of model data moving toward the processor. (semiconductor.samsung.com)
HBM4E pushes the package further. Samsung’s current product information describes configurations reaching up to 64 gigabytes, 16 memory layers, 16 gigabits per second per pin, and 4 terabytes per second of bandwidth in a single 16-high stack. More layers mean more capacity, but they also leave less room for mistakes in thinning, alignment, heat management, and final assembly.
Why 2.5 times more cleaning can signal twice the output
The important caveat is that 50,000 cleaned carriers do not equal 50,000 finished HBM stacks. A glass carrier can be reused, and its cleaning frequency depends on the process flow, the number of wafers loaded at once, the time spent in each step, and the factory’s yield. Yield is the share of manufactured parts that pass inspection and can become sellable products.
Even with those variables, cleaning volume is a useful capacity signal. A carrier sitting in a cleaning queue cannot support the next wafer. More carriers in circulation, or faster turnaround from an outsourced cleaning partner, can help Samsung run more production batches without waiting for support hardware to become available.
That is how total wafer input could rise by roughly 40% while HBM4 and HBM4E output grows by more than two times, as the report expects. A larger portion of Samsung’s capacity would be directed toward newer, higher-layer products, while the supporting carrier operation expands ahead of the ramp. The glass number is therefore better understood as a leading indicator of factory preparation than as a direct shipment counter. (en.sedaily.com)
Samples are not the same as high-volume production
Samsung’s public timeline helps explain why the distinction matters. After beginning HBM4 production in February, the company said in its second-quarter 2026 results that it had shipped HBM4E samples to major customers. A sample allows a customer to test electrical behavior, thermal performance, software compatibility, and physical integration with an AI accelerator. It does not yet prove that the same design can be produced at high volume with strong yields.
Samsung also said demand for HBM and other server memories remained strong while supply constraints were expected to continue. That creates a powerful incentive to expand capacity, but the final outcome still depends on customer qualification, packaging throughput, test capacity, and the number of good dies produced from each wafer.
The bigger meaning for AI servers
An AI accelerator can perform enormous amounts of mathematical work, but it still needs a steady stream of model weights—the learned numbers inside an AI model—and intermediate results called activations. If memory cannot deliver that data quickly enough, expensive compute resources sit idle. HBM4’s wide interface and stacked structure are designed to reduce that memory bottleneck.
More Samsung HBM4 and HBM4E supply could therefore support a larger number of AI systems, especially as server builders move toward accelerators that demand more capacity and bandwidth. But the glass carrier story also shows why these products are difficult to scale: HBM is not only a DRAM problem. It is a coordinated exercise in wafer thinning, logic integration, thermal control, stacking, packaging, and quality inspection.
The glass is not the product. It is the scaffolding that lets the product exist. When a manufacturer starts preparing far more scaffolding, it may be an early glimpse of a much larger construction project already taking shape inside the factory.
Comments (0)
No comments yet. Be the first to respond!
Leave a Comment
Your comment will be visible after review.