</> HitReader
Blog Explore About

Category: ai infrastructure

Qwen3.8-27B Hits ~1,500 Tokens per Second on Cerebras
ai infrastructure Sep 03, 2026 5 min read

Qwen3.8-27B Hits ~1,500 Tokens per Second on Cerebras

Qwen3.8-27B is now listed on Cerebras public endpoints at roughly 1,500 generated tokens per second. This guide explains what the speed means, how reasoning and context limits affect real latency, and how to make a first API call.
by ahsan
#cerebras #developer tools #llm inference #multimodal ai #qwen
Run GLM-5.2 on a Slow PC with colibrì (Disk-Streamed MoE)
ai infrastructure Jul 10, 2026 7 min read

Run GLM-5.2 on a Slow PC with colibrì (Disk-Streamed MoE)

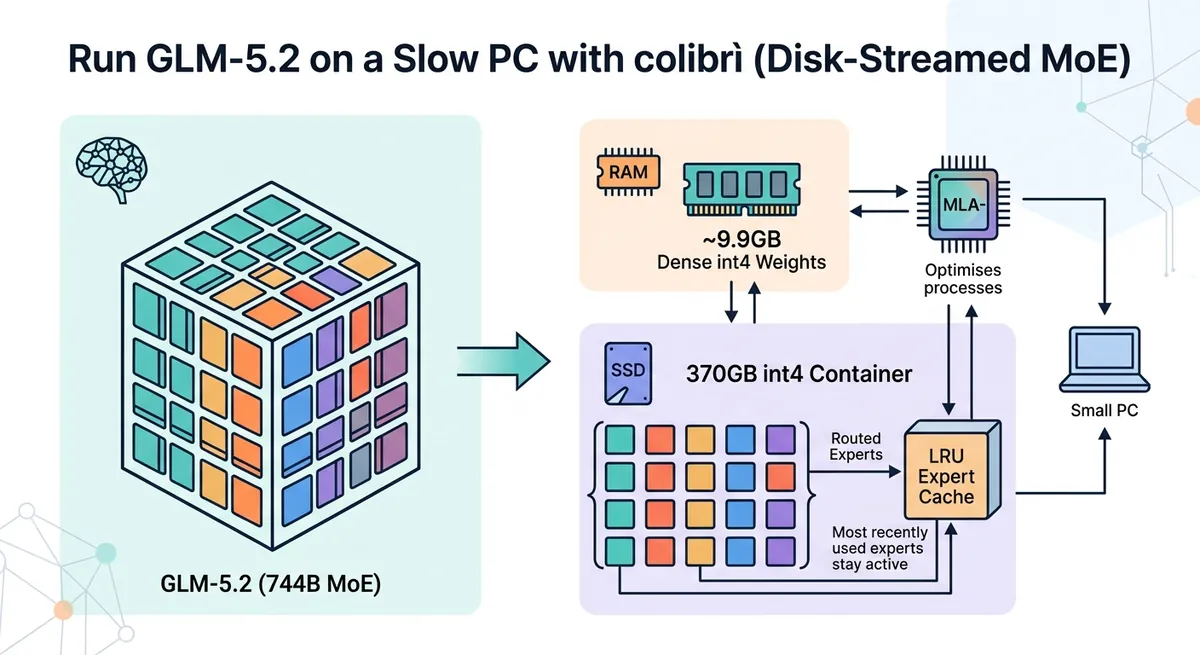
colibrì runs GLM-5.2 (744B MoE) on consumer hardware by keeping ~9.9GB of dense int4 weights in RAM and streaming routed experts from a ~370GB int4 container on disk. It uses an LRU expert cache, MLA-style compressed KV caching, and native MTP speculative decoding to improve interaction speed once caches are warm.

by ahsan
#cpu inference #glm-5.2 #moe #quantization #systems

Categories

  • artificial intelligence
  • machine learning
  • software engineering
  • cybersecurity
  • web development
  • developer tools
  • open source
  • embedded systems
Explore all →

Tags

#open-source #artificial intelligence #ai agents #privacy #cybersecurity #llm #machine learning #large language models #linux #rust #ai #android
Explore all →

© 2026 HitReader.

About Explore Terms Privacy Facebook