</> HitReader
Blog Explore About

Tag: #quantization

How a 125B Model Reaches 100 Tok/s on an RTX 4090
artificial intelligence Oct 04, 2026 6 min read

How a 125B Model Reaches 100 Tok/s on an RTX 4090

A 125B model can run quickly on a gaming PC when the system treats the GPU, RAM, CPU, and SSD as one memory hierarchy. This guide explains the Strata setup, quantization, expert caching, and speculative decoding behind fast Qwen3.8-Flash-Next inference.
by ahsan
#consumer hardware #gpu inference #local ai #quantization #qwen
machine learning Aug 18, 2026 6 min read

Turbovec: Google’s TurboQuant Vector Search in Rust

Turbovec is a Rust vector index built on Google’s TurboQuant. It stores high-dimensional embeddings in 2–4 bits per coordinate, avoids a separate training phase, and uses SIMD-friendly layouts for fast similarity search.

by ahsan
#machine learning #quantization #rust #simd #vector search
Qwen3.8-27B FP8: FP8 Quantization, Thinking Control, and 1M Context in Practice
machine learning Aug 14, 2026 7 min read

Qwen3.8-27B FP8: FP8 Quantization, Thinking Control, and 1M Context in Practice

Qwen3.8-27B-FP8 packages a 27B vision-language model as fine-grained FP8 (block size 128) weights. It adds practical controls like `reasoning_effort` and `preserve_thinking`, plus native 262K context with extensibility toward 1M tokens for long-horizon tasks.

by ahsan
#inference #llm #machine learning #multimodal #quantization
H3-metal: Native MiniMax‑H3 Inference on Apple Silicon (Metal)
machine learning Aug 11, 2026 7 min read

H3-metal: Native MiniMax‑H3 Inference on Apple Silicon (Metal)

h3-metal is a native MiniMax‑H3 inference engine for Apple Silicon built on Metal. It combines BF16/int8 compute paths, unified-memory-aware buffer reuse, and a stateful interactive workflow to generate video and audio locally.

by ahsan
#applesilicon #inference #metal #open-source #quantization
Muse Glimmer 30B: An Open Agentic Coding Model You Can Run Locally
machine learning Aug 10, 2026 7 min read

Muse Glimmer 30B: An Open Agentic Coding Model You Can Run Locally

Muse Glimmer is Meta’s open-weight 30B agentic model released under Apache 2.0, designed to run locally for coding and tool-using workflows. Its local feasibility comes from quantization for memory fit and DFlash-based speculative decoding for faster generation.

by ahsan
#llm #local ai #open-weights #quantization #speculative decoding
Run GLM-5.2 on a Slow PC with colibrì (Disk-Streamed MoE)
ai infrastructure Jul 10, 2026 7 min read

Run GLM-5.2 on a Slow PC with colibrì (Disk-Streamed MoE)

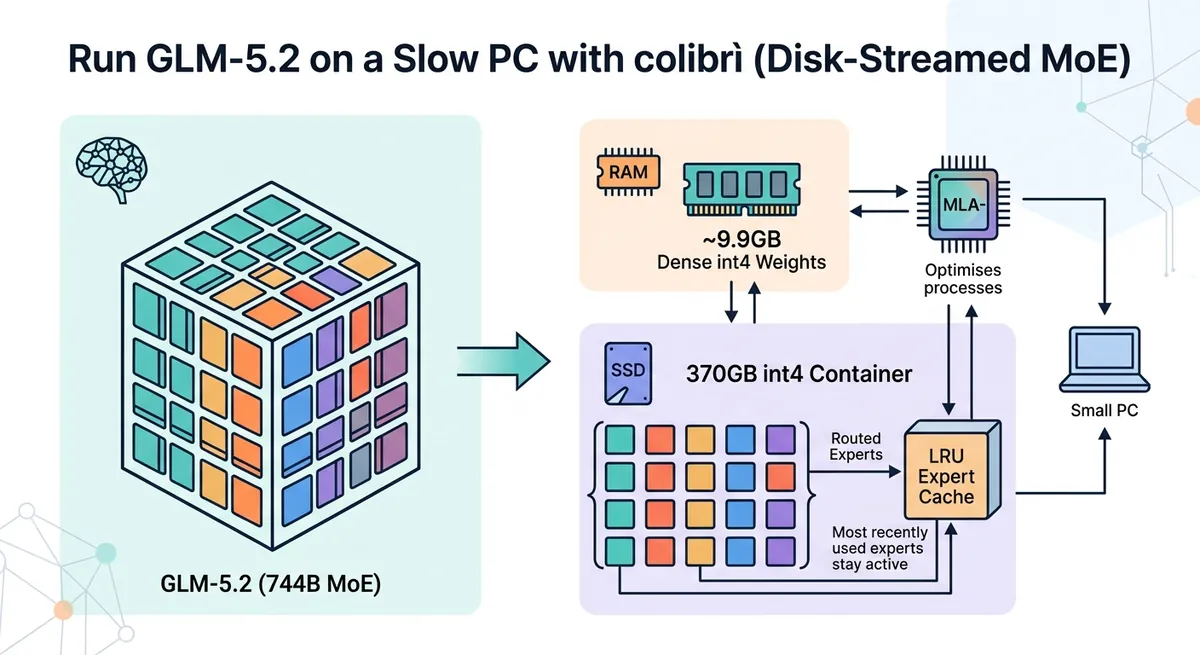
colibrì runs GLM-5.2 (744B MoE) on consumer hardware by keeping ~9.9GB of dense int4 weights in RAM and streaming routed experts from a ~370GB int4 container on disk. It uses an LRU expert cache, MLA-style compressed KV caching, and native MTP speculative decoding to improve interaction speed once caches are warm.

by ahsan
#cpu inference #glm-5.2 #moe #quantization #systems

Categories

  • artificial intelligence
  • machine learning
  • software engineering
  • cybersecurity
  • web development
  • developer tools
  • open source
  • embedded systems
Explore all →

Tags

#open-source #artificial intelligence #ai agents #privacy #cybersecurity #llm #machine learning #large language models #linux #rust #ai #android
Explore all →

© 2026 HitReader.

About Explore Terms Privacy Facebook