</> HitReader
Blog Explore About

Category: deep tech

How to Run SOTA LLMs Locally: GPUs, PCIe, and Practical Setup
deep tech Jul 03, 2026 7 min read

How to Run SOTA LLMs Locally: GPUs, PCIe, and Practical Setup

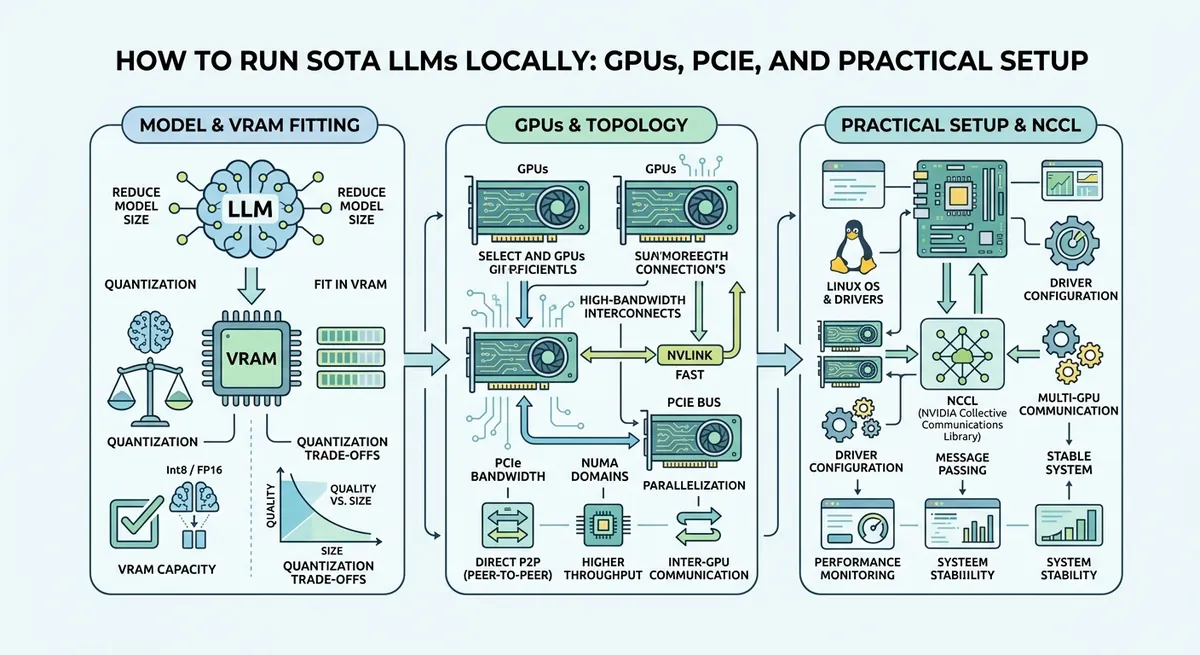
Running SOTA LLMs locally is a systems problem, not just a model download. VRAM and quantization must fit, and multi-GPU speed depends on PCIe topology, P2P routing, and NCCL stability.

by ahsan
#llm inference #local llms #multi-gpu #nvidia nccl #pcie

Categories

  • artificial intelligence
  • machine learning
  • software engineering
  • cybersecurity
  • open source
  • web development
  • developer tools
  • embedded systems
Explore all →

Tags

#open-source #artificial intelligence #privacy #ai agents #cybersecurity #llm #machine learning #linux #rust #ai #large language models #android
Explore all →

© 2026 HitReader.

About Explore Terms Privacy Facebook