How to Run SOTA LLMs Locally: GPUs, PCIe, and Practical Setup
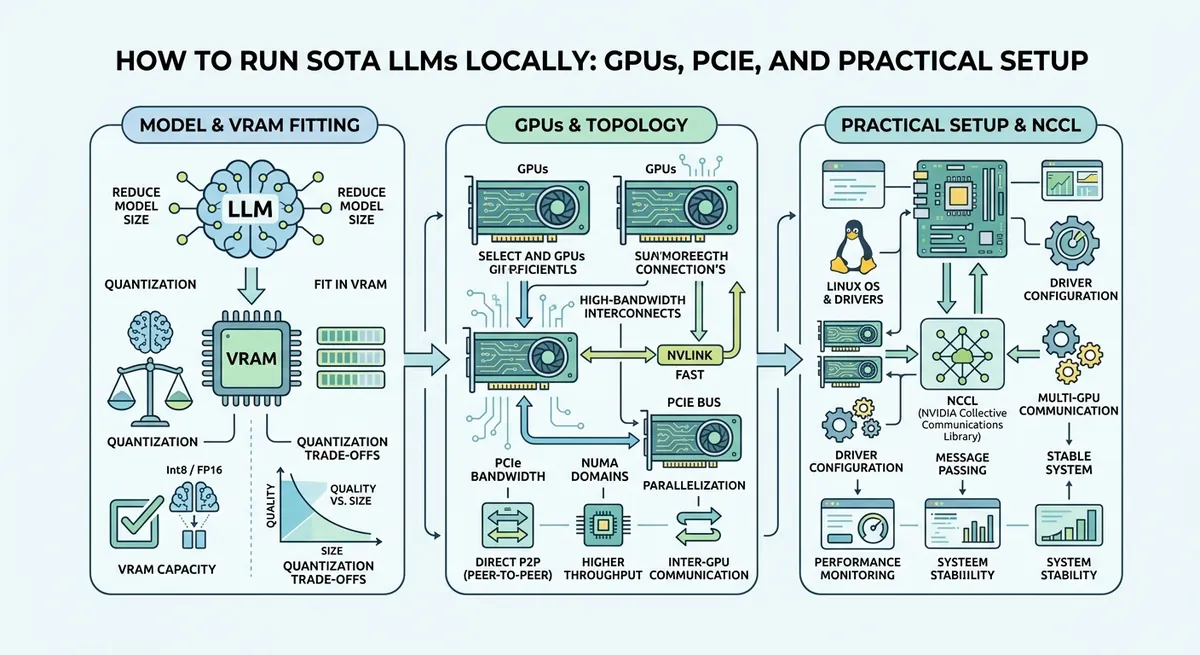
Running SOTA LLMs locally is a systems problem, not just a model download. VRAM and quantization must fit, and multi-GPU speed depends on PCIe topology, P2P routing, and NCCL stability.
Running SOTA LLMs locally is a systems problem, not just a model download. VRAM and quantization must fit, and multi-GPU speed depends on PCIe topology, P2P routing, and NCCL stability.

Qwen 3.6 27B stands out as a practical local model: high enough quality for day-to-day development and strong performance with llama.cpp. This guide explains why 27B is the sweet spot and shows how to run it (with MTP) and integrate it into coding tools.